Generative AI
Weaviate's integration with Azure OpenAI's APIs allows you to access their models' capabilities directly from Weaviate.
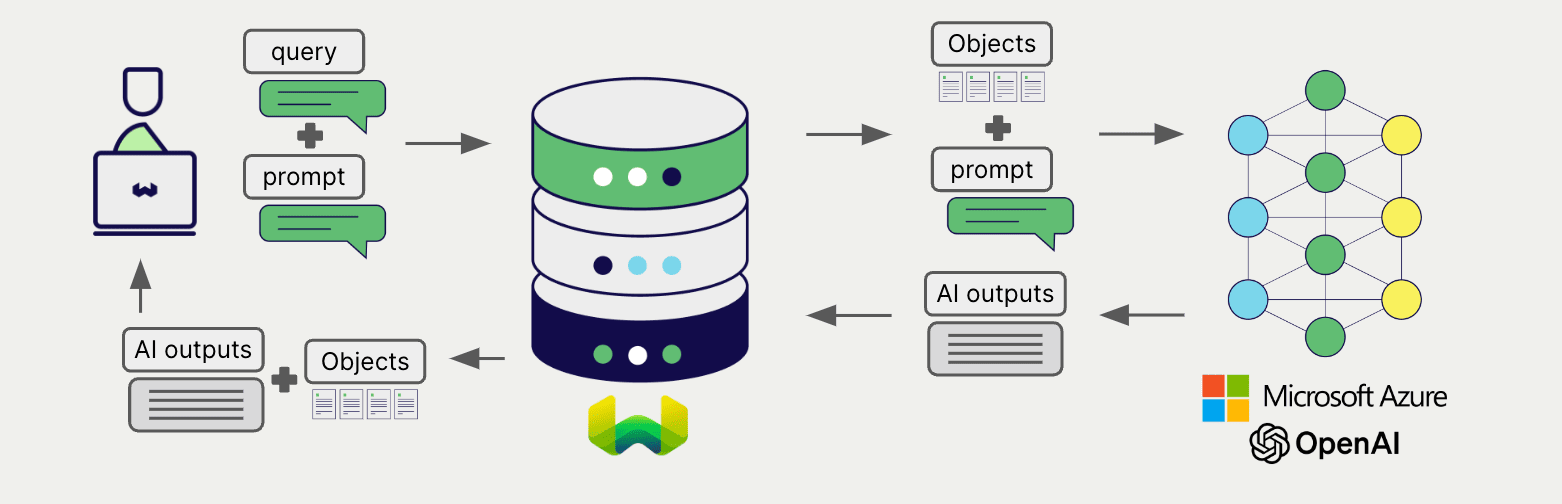
Configure a Weaviate collection to use a generative AI model with Azure OpenAI. Weaviate will perform retrieval augmented generation (RAG) using the specified model and your Azure OpenAI API key.
More specifically, Weaviate will perform a search, retrieve the most relevant objects, and then pass them to the Azure OpenAI generative model to generate outputs.
Requirements
Section titled “Requirements”Weaviate configuration
Section titled “Weaviate configuration”Your Weaviate instance must be configured with the Azure OpenAI generative AI integration (generative-openai) module.
For Weaviate Cloud (WCD) users
This integration is enabled by default on Weaviate Cloud (WCD) instances.
For self-hosted users
- Check the cluster metadata to verify if the module is enabled.
- Follow the how-to configure modules guide to enable the module in Weaviate.
API credentials
Section titled “API credentials”You must provide a valid Azure OpenAI API key to Weaviate for this integration. Go to Azure OpenAI to sign up and obtain an API key.
Provide the API key to Weaviate using one of the following methods:
- Set the
AZURE_APIKEYenvironment variable that is available to Weaviate. - Provide the API key at runtime, as shown in the examples below.
# Recommended: save sensitive data as environment variables
azure_key = os.getenv("AZURE_API_KEY")const azureApiKey = process.env.AZURE_API_KEY || ''; // Replace with your inference API keyConfigure collection
Section titled “Configure collection”Configure a Weaviate index as follows to use an OpenAI Azure generative model.
To select the model, specify the Azure resource name.
from weaviate.classes.config import Configureclient.collections.create( "DemoCollection", generative_config=Configure.Generative.azure_openai( resource_name="<azure-resource-name>", deployment_id="<azure-deployment-id>", ) # Additional parameters not shown)await client.collections.create({ name: 'DemoCollection', generative: weaviate.configure.generative.azureOpenAI({ resourceName: '<azure-resource-name>', deploymentId: '<azure-deployment-id>', }), // Additional parameters not shown});Generative parameters
Section titled “Generative parameters”Configure the following generative parameters to customize the model behavior.
from weaviate.classes.config import Configureclient.collections.create( "DemoCollection", generative_config=Configure.Generative.azure_openai( resource_name="<azure-resource-name>", deployment_id="<azure-deployment-id>", # # These parameters are optional # frequency_penalty=0, # max_tokens=500, # presence_penalty=0, # temperature=0.7, # top_p=0.7, # base_url="<custom-azure-url>" ) # Additional parameters not shown)await client.collections.create({ name: 'DemoCollection', generative: weaviate.configure.generative.azureOpenAI({ resourceName: '<azure-resource-name>', deploymentId: '<azure-deployment-id>', // These parameters are optional // frequencyPenalty: 0, // maxTokens: 500, // presencePenalty: 0, // temperature: 0.7, // topP: 0.7, }), // Additional parameters not shown});For further details on these parameters, see consult the Azure OpenAI API documentation.
Header parameters
Section titled “Header parameters”You can provide the API key as well as some optional parameters at runtime through additional headers in the request. The following headers are available:
X-Azure-Api-Key: The Azure API key.X-Azure-Deployment-Id: The Azure deployment ID.X-Azure-Resource-Name: The Azure resource name.
Any additional headers provided at runtime will override the existing Weaviate configuration.
Provide the headers as shown in the API credentials examples above.
Retrieval augmented generation
Section titled “Retrieval augmented generation”After configuring the generative AI integration, perform RAG operations, either with the single prompt or grouped task method.
Single prompt
Section titled “Single prompt”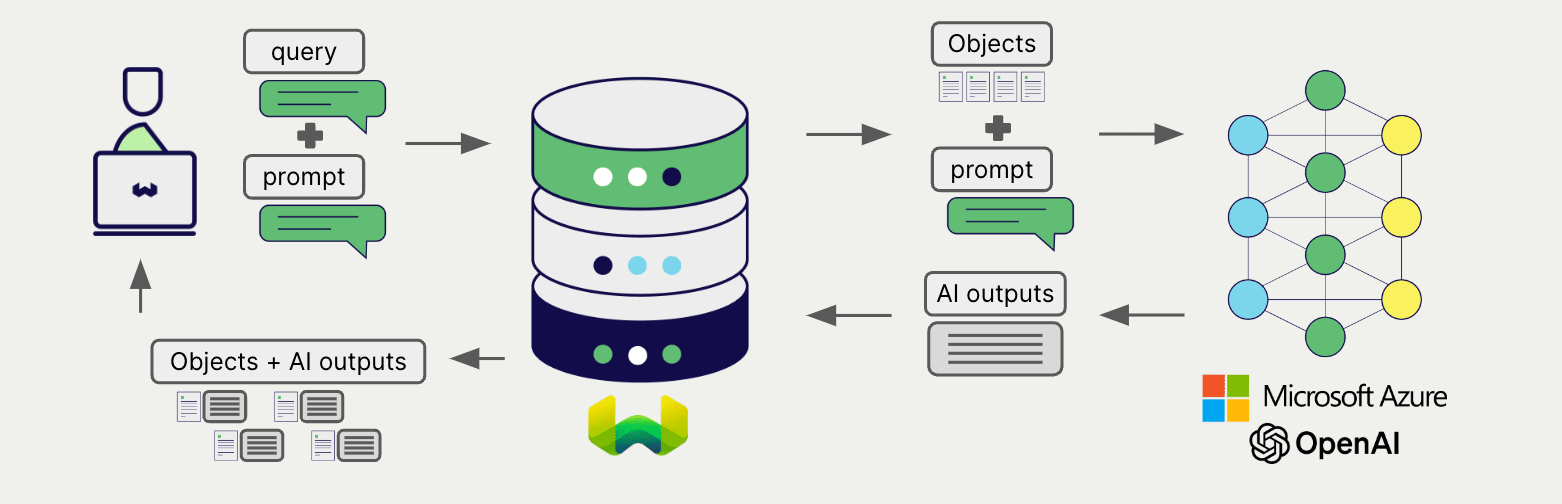
To generate text for each object in the search results, use the single prompt method.
The example below generates outputs for each of the n search results, where n is specified by the limit parameter.
When creating a single prompt query, use braces {} to interpolate the object properties you want Weaviate to pass on to the language model. For example, to pass on the object's title property, include {title} in the query.
collection = client.collections.use("DemoCollection")response = collection.generate.near_text( query="A holiday film", # The model provider integration will automatically vectorize the query single_prompt="Translate this into French: {title}", limit=2)for obj in response.objects: print(obj.properties["title"]) print(f"Generated output: {obj.generated}") # Note that the generated output is per objectlet response;
const myCollection = client.collections.use("DemoCollection");Grouped task
Section titled “Grouped task”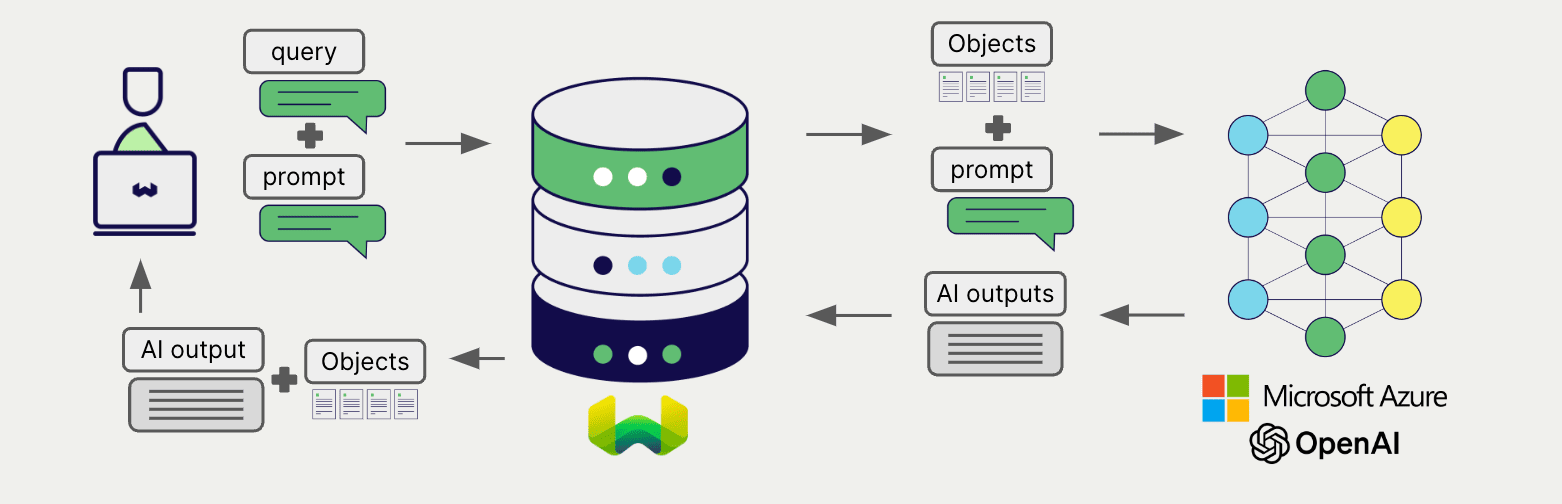
To generate one text for the entire set of search results, use the grouped task method.
In other words, when you have n search results, the generative model generates one output for the entire group.
collection = client.collections.use("DemoCollection")response = collection.generate.near_text( query="A holiday film", # The model provider integration will automatically vectorize the query grouped_task="Write a fun tweet to promote readers to check out these films.", limit=2)print(f"Generated output: {response.generative.text}") # Note that the generated output is per queryfor obj in response.objects: print(obj.properties["title"])let response;
const myCollection = client.collections.use("DemoCollection");References
Section titled “References”Available models
Section titled “Available models”See the Azure OpenAI documentation for a list of available models and their regional availability.
Further resources
Section titled “Further resources”Other integrations
Section titled “Other integrations”Code examples
Section titled “Code examples”Once the integrations are configured at the collection, the data management and search operations in Weaviate work identically to any other collection. See the following model-agnostic examples:
- The How-to: Manage collections and How-to: Manage objects guides show how to perform data operations (i.e. create, read, update, delete collections and objects within them).
- The How-to: Query & Search guides show how to perform search operations (i.e. vector, keyword, hybrid) as well as retrieval augmented generation.
References
Section titled “References”- Azure OpenAI API documentation
- Azure OpenAI models and availability
Questions and feedback
Section titled “Questions and feedback”Have a question or feedback? Here's how to reach us.