Multimodal Embeddings
Weaviate's integration with TwelveLabs' APIs allows you to access their models' capabilities directly from Weaviate.
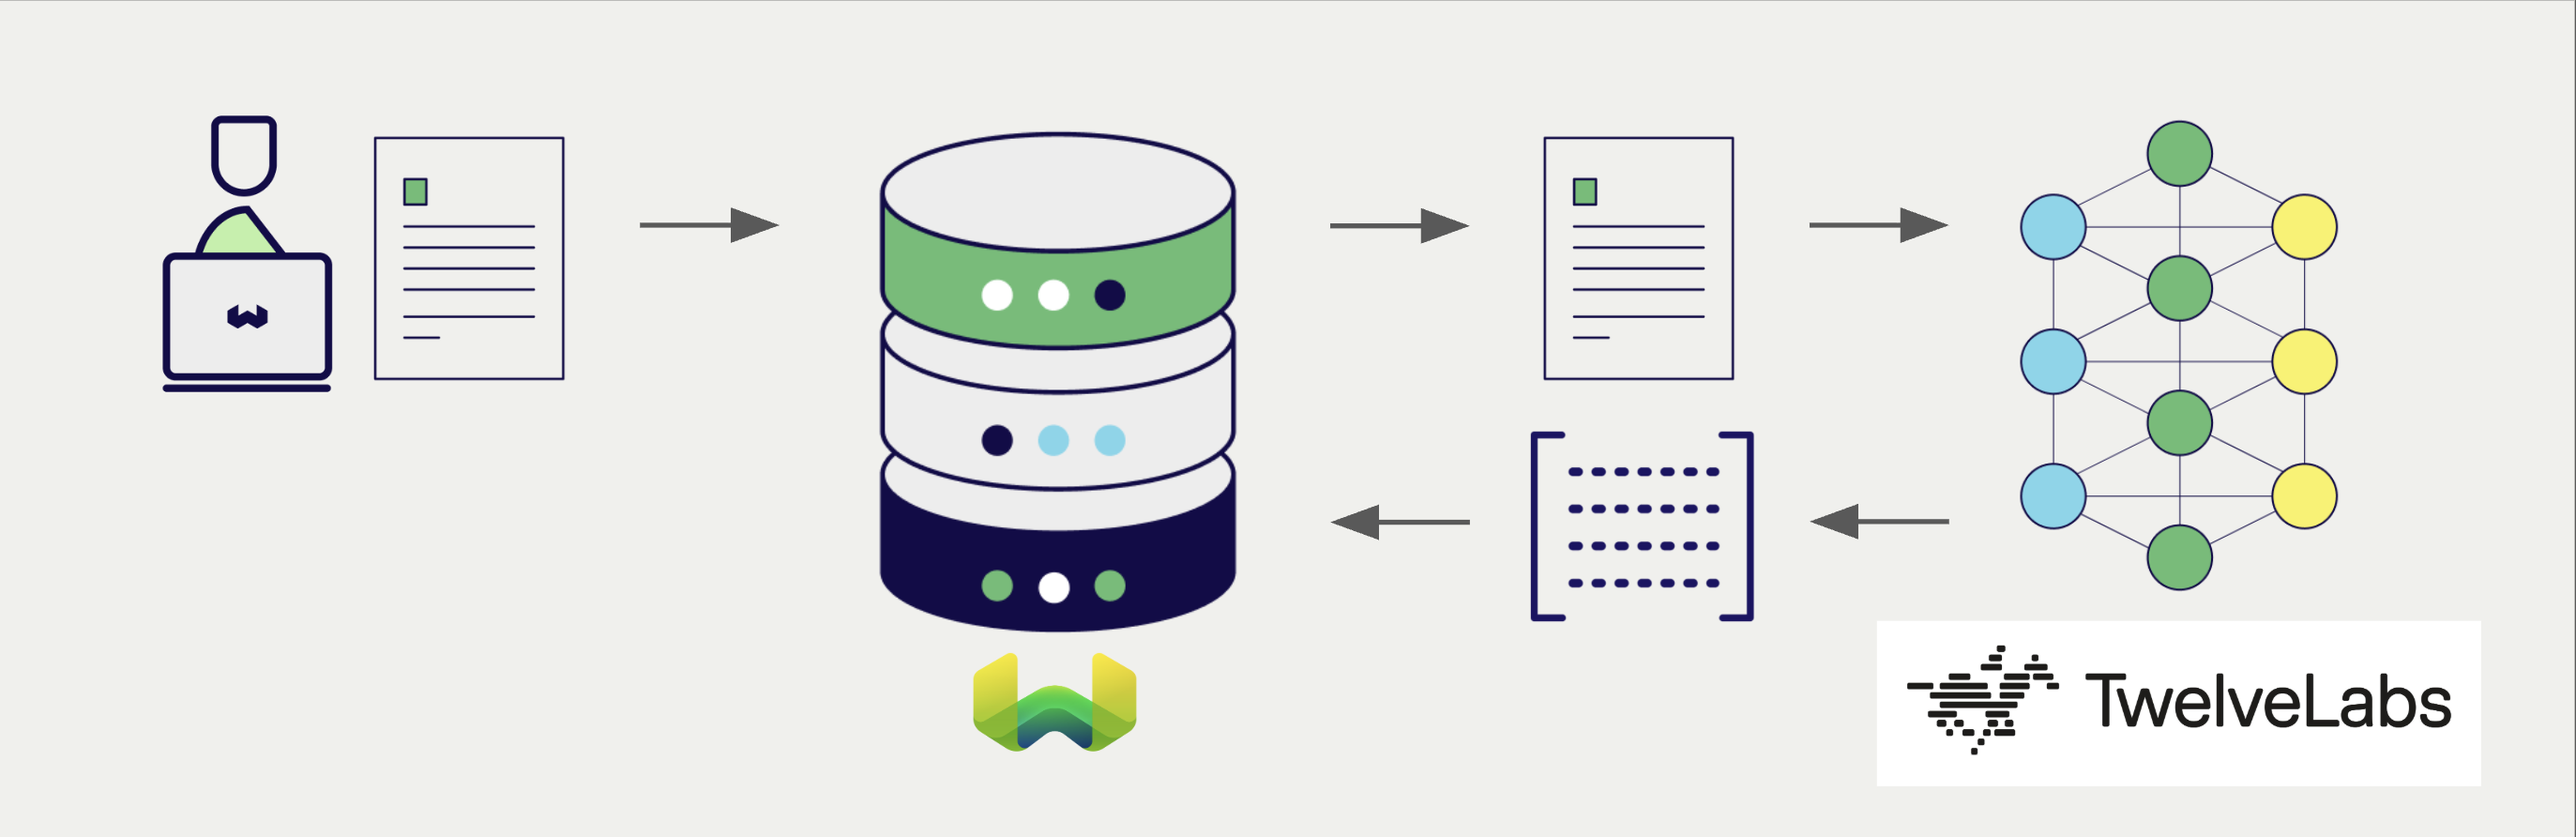
Configure a Weaviate vector index to use a TwelveLabs embedding model, and Weaviate will generate embeddings for various operations using the specified model and your TwelveLabs API key. This feature is called the vectorizer.
At import time, Weaviate generates multimodal object embeddings and saves them into the index. For vector and hybrid search operations, Weaviate converts text queries into embeddings. Multimodal search operations are also supported.
Requirements
Section titled “Requirements”Weaviate configuration
Section titled “Weaviate configuration”Your Weaviate instance must be configured with the TwelveLabs vectorizer integration (multi2vec-twelvelabs) module.
For Weaviate Cloud (WCD) users
This integration is enabled by default on Weaviate Cloud (WCD) instances.
For self-hosted users
- Check the cluster metadata to verify if the module is enabled.
- Follow the how-to configure modules guide to enable the module in Weaviate.
API credentials
Section titled “API credentials”You must provide a valid TwelveLabs API key to Weaviate for this integration. Go to TwelveLabs to sign up and obtain an API key.
Provide the API key to Weaviate using one of the following methods:
- Set the
TWELVELABS_APIKEYenvironment variable that is available to Weaviate. - Provide the API key at runtime, as shown in the examples below.
# Recommended: save sensitive data as environment variables
twelvelabs_key = os.getenv("TWELVELABS_APIKEY")curl http://localhost:8080/v1/graphql \
-H "Content-Type: application/json" \
-H "X-Twelvelabs-Api-Key: $TWELVELABS_APIKEY" \
-H "X-Twelvelabs-Baseurl: https://api.twelvelabs.io/v1.3" \
-d '{"query": "{ Get { DemoCollection(nearText: {concepts: [\"A holiday film\"]}, limit: 2) { title } } }"}'The X-Twelvelabs-Baseurl header is optional. It overrides the base URL that is set in the collection definition for the duration of the request.
Configure the vectorizer
Section titled “Configure the vectorizer”Configure a Weaviate index as follows to use a TwelveLabs embedding model.
Name the properties that hold your text in textFields, and the properties that hold your base64 encoded images in imageFields. Set at least one of the two. A collection that names no fields cannot produce a vector, and inserts into it fail with a more than one embedding found for object error.
from weaviate.classes.config import Configure, DataType, Multi2VecField, Propertyclient.collections.create( "DemoCollection", properties=[ Property(name="title", data_type=DataType.TEXT), Property(name="poster", data_type=DataType.BLOB), ], vector_config=[ Configure.Vectors.multi2vec_twelvelabs( name="title_vector", # Define the fields to be used for the vectorization - using image_fields, text_fields image_fields=[ Multi2VecField(name="poster", weight=0.9) ], text_fields=[ Multi2VecField(name="title", weight=0.1) ], ) ], # Additional parameters not shown)curl -X POST http://localhost:8080/v1/schema \
-H "Content-Type: application/json" \
-d '{
"class": "DemoCollection",
"properties": [
{"name": "title", "dataType": ["text"]},
{"name": "poster", "dataType": ["blob"]}
],
"vectorConfig": {
"title_vector": {
"vectorizer": {
"multi2vec-twelvelabs": {
"textFields": ["title"],
"imageFields": ["poster"],
"weights": {
"textFields": [0.1],
"imageFields": [0.9]
}
}
},
"vectorIndexType": "hnsw"
}
}
}'Select a model
Section titled “Select a model”You can specify one of the available models for the vectorizer to use, as shown in the following configuration example.
from weaviate.classes.config import Configure, DataType, Multi2VecField, Propertyclient.collections.create( "DemoCollection", properties=[ Property(name="title", data_type=DataType.TEXT), Property(name="poster", data_type=DataType.BLOB), ], vector_config=[ Configure.Vectors.multi2vec_twelvelabs( name="title_vector", model="marengo3.0", # Define the fields to be used for the vectorization - using image_fields, text_fields image_fields=[ Multi2VecField(name="poster", weight=0.9) ], text_fields=[ Multi2VecField(name="title", weight=0.1) ], ) ], # Additional parameters not shown)curl -X POST http://localhost:8080/v1/schema \
-H "Content-Type: application/json" \
-d '{
"class": "DemoCollection",
"properties": [
{"name": "title", "dataType": ["text"]},
{"name": "poster", "dataType": ["blob"]}
],
"vectorConfig": {
"title_vector": {
"vectorizer": {
"multi2vec-twelvelabs": {
"textFields": ["title"],
"imageFields": ["poster"],
"model": "marengo3.0"
}
},
"vectorIndexType": "hnsw"
}
}
}'You can specify one of the available models for Weaviate to use. The default model is used if no model is specified.
Vectorization behavior
Weaviate follows the collection configuration and a set of predetermined rules to vectorize objects.
Unless specified otherwise in the collection definition, the default behavior is to:
- Only vectorize properties that use the
textortext[]data type (unless skipped) - Sort properties in alphabetical (a-z) order before concatenating values
- If
vectorizePropertyNameistrue(falseby default) prepend the property name to each property value - Join the (prepended) property values with spaces
- Prepend the class name (unless
vectorizeClassNameisfalse) - Convert the produced string to lowercase
Vectorizer parameters
Section titled “Vectorizer parameters”The following examples show how to configure TwelveLabs-specific options.
from weaviate.classes.config import Configure, DataType, Multi2VecField, Propertyclient.collections.create( "DemoCollection", properties=[ Property(name="title", data_type=DataType.TEXT), Property(name="poster", data_type=DataType.BLOB), ], vector_config=[ Configure.Vectors.multi2vec_twelvelabs( name="title_vector", # Define the fields to be used for the vectorization - using image_fields, text_fields image_fields=[ Multi2VecField(name="poster", weight=0.9) ], text_fields=[ Multi2VecField(name="title", weight=0.1) ], # Further options # model="marengo3.0", # base_url="https://api.twelvelabs.io/v1.3", ) ], # Additional parameters not shown)curl -X POST http://localhost:8080/v1/schema \
-H "Content-Type: application/json" \
-d '{
"class": "DemoCollection",
"properties": [
{"name": "title", "dataType": ["text"]},
{"name": "poster", "dataType": ["blob"]}
],
"vectorConfig": {
"title_vector": {
"vectorizer": {
"multi2vec-twelvelabs": {
"textFields": ["title"],
"imageFields": ["poster"],
"weights": {
"textFields": [0.1],
"imageFields": [0.9]
},
"model": "marengo3.0",
"baseURL": "https://api.twelvelabs.io/v1.3"
}
},
"vectorIndexType": "hnsw"
}
}
}'The collection definition accepts the following settings:
| Setting | Description |
|---|---|
textFields |
Names of the text and text[] properties to vectorize. Each element of a text[] property is vectorized separately. |
imageFields |
Names of the properties that hold base64 encoded images, typically blob properties. A text[] property listed here is ignored. |
weights |
Relative weights for combining the field vectors, given as textFields and imageFields arrays. Each array must have the same number of entries as the field list it weights. The weights are normalized so that they sum to 1. If no weights are set, all fields are weighted equally. |
model |
The model to use. The default is marengo3.0. |
baseURL |
The base URL of the TwelveLabs API. The default is https://api.twelvelabs.io/v1.3. |
In the Python client, these settings are named text_fields, image_fields, model and base_url. Weights are set per field with Multi2VecField(name=..., weight=...).
For further details on model parameters, see the TwelveLabs documentation.
Data import
Section titled “Data import”After configuring the vectorizer, import data into Weaviate. Weaviate generates embeddings for text and image objects using the specified model.
Provide image data as a base64 encoded string. A data:<mediatype>;base64, prefix is accepted and stripped before decoding. A property that is listed in imageFields but does not hold valid base64 data fails the import with a decode base64 image error.
collection = client.collections.use("DemoCollection")with collection.batch.fixed_size(batch_size=200) as batch: for src_obj in source_objects: poster_b64 = url_to_base64(src_obj["poster_path"]) weaviate_obj = { "title": src_obj["title"], "poster": poster_b64 # Add the image in base64 encoding } # The model provider integration will automatically vectorize the object batch.add_object( properties=weaviate_obj, # vector=vector # Optionally provide a pre-obtained vector )Searches
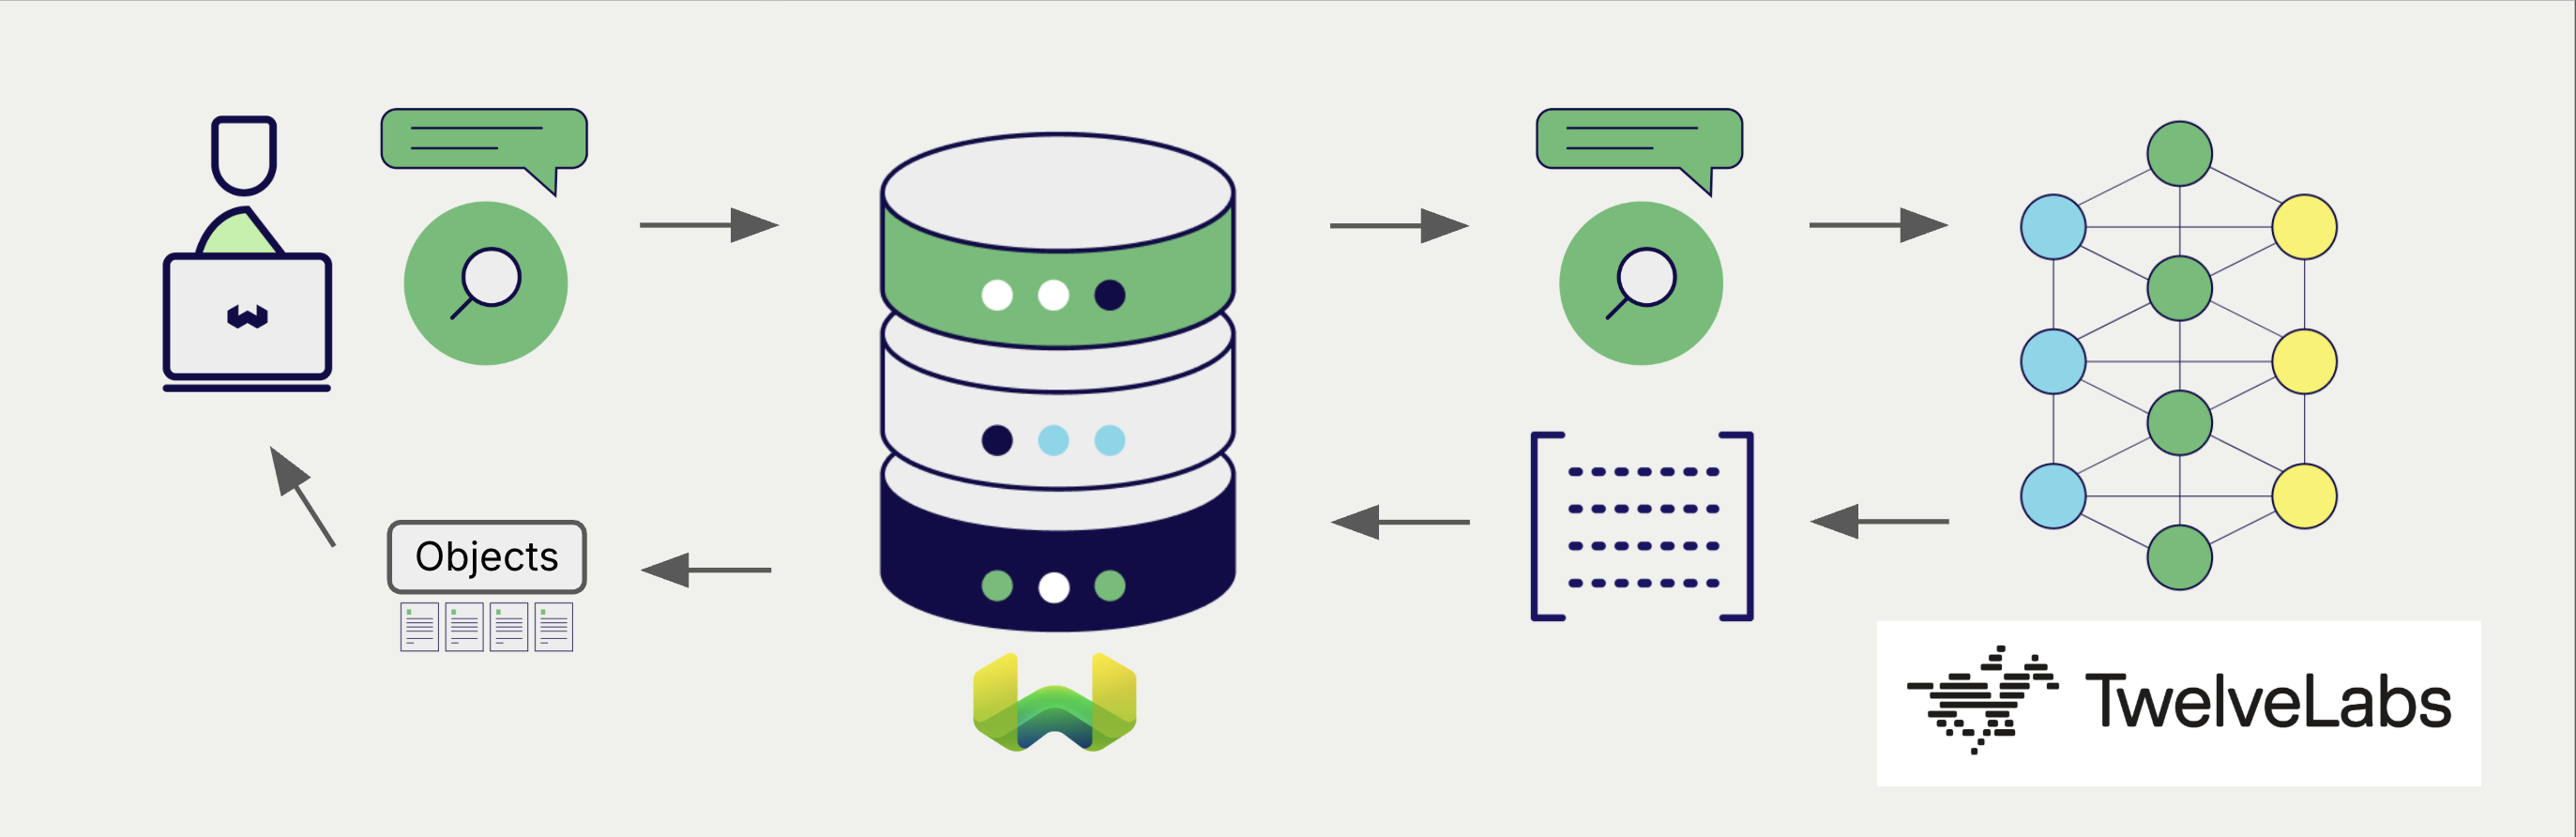
Section titled “Searches”Once the vectorizer is configured, Weaviate will perform vector and hybrid search operations using the specified TwelveLabs model.
The examples below use the Python client. Search operations are not specific to this integration, so see the How-to: Query & Search guides for the equivalent examples in the other client libraries.
Vector (near text) search
Section titled “Vector (near text) search”When you perform a vector search, Weaviate converts the text query into an embedding using the specified model and returns the most similar objects from the database.
The query below returns the n most similar objects from the database, set by limit.
collection = client.collections.use("DemoCollection")response = collection.query.near_text( query="A holiday film", # The model provider integration will automatically vectorize the query limit=2)for obj in response.objects: print(obj.properties["title"])Hybrid search
Section titled “Hybrid search”When you perform a hybrid search, Weaviate converts the text query into an embedding using the specified model and returns the best scoring objects from the database.
The query below returns the n best scoring objects from the database, set by limit.
collection = client.collections.use("DemoCollection")response = collection.query.hybrid( query="A holiday film", # The model provider integration will automatically vectorize the query limit=2)for obj in response.objects: print(obj.properties["title"])Vector (near image) search
Section titled “Vector (near image) search”When you perform a near image search, Weaviate converts the query into an embedding using the specified model and returns the most similar objects from the database.
To perform a near image search, convert the image query into a base64 string and pass it to the search query.
The query below returns the n most similar objects to the input image from the database, set by limit.
def url_to_base64(url):
    import requests
    import base64

    image_response = requests.get(url)
    content = image_response.content
    return base64.b64encode(content).decode("utf-8")
References
Section titled “References”Available models
Section titled “Available models”The default model is marengo3.0, which produces 512-dimensional vectors.
Weaviate does not validate the model name, so you can set any model that the TwelveLabs embedding endpoint accepts for your account. Weaviate does not publish the list of accepted names; see the TwelveLabs documentation on creating embeddings for the models that are currently available.
Further resources
Section titled “Further resources”Code examples
Section titled “Code examples”Once the integrations are configured at the collection, the data management and search operations in Weaviate work identically to any other collection. See the following model-agnostic examples:
- The How-to: Manage collections and How-to: Manage objects guides show how to perform data operations (i.e. create, read, update, delete collections and objects within them).
- The How-to: Query & Search guides show how to perform search operations (i.e. vector, keyword, hybrid) as well as retrieval augmented generation.
External resources
Section titled “External resources”Questions and feedback
Section titled “Questions and feedback”Have a question or feedback? Here's how to reach us.